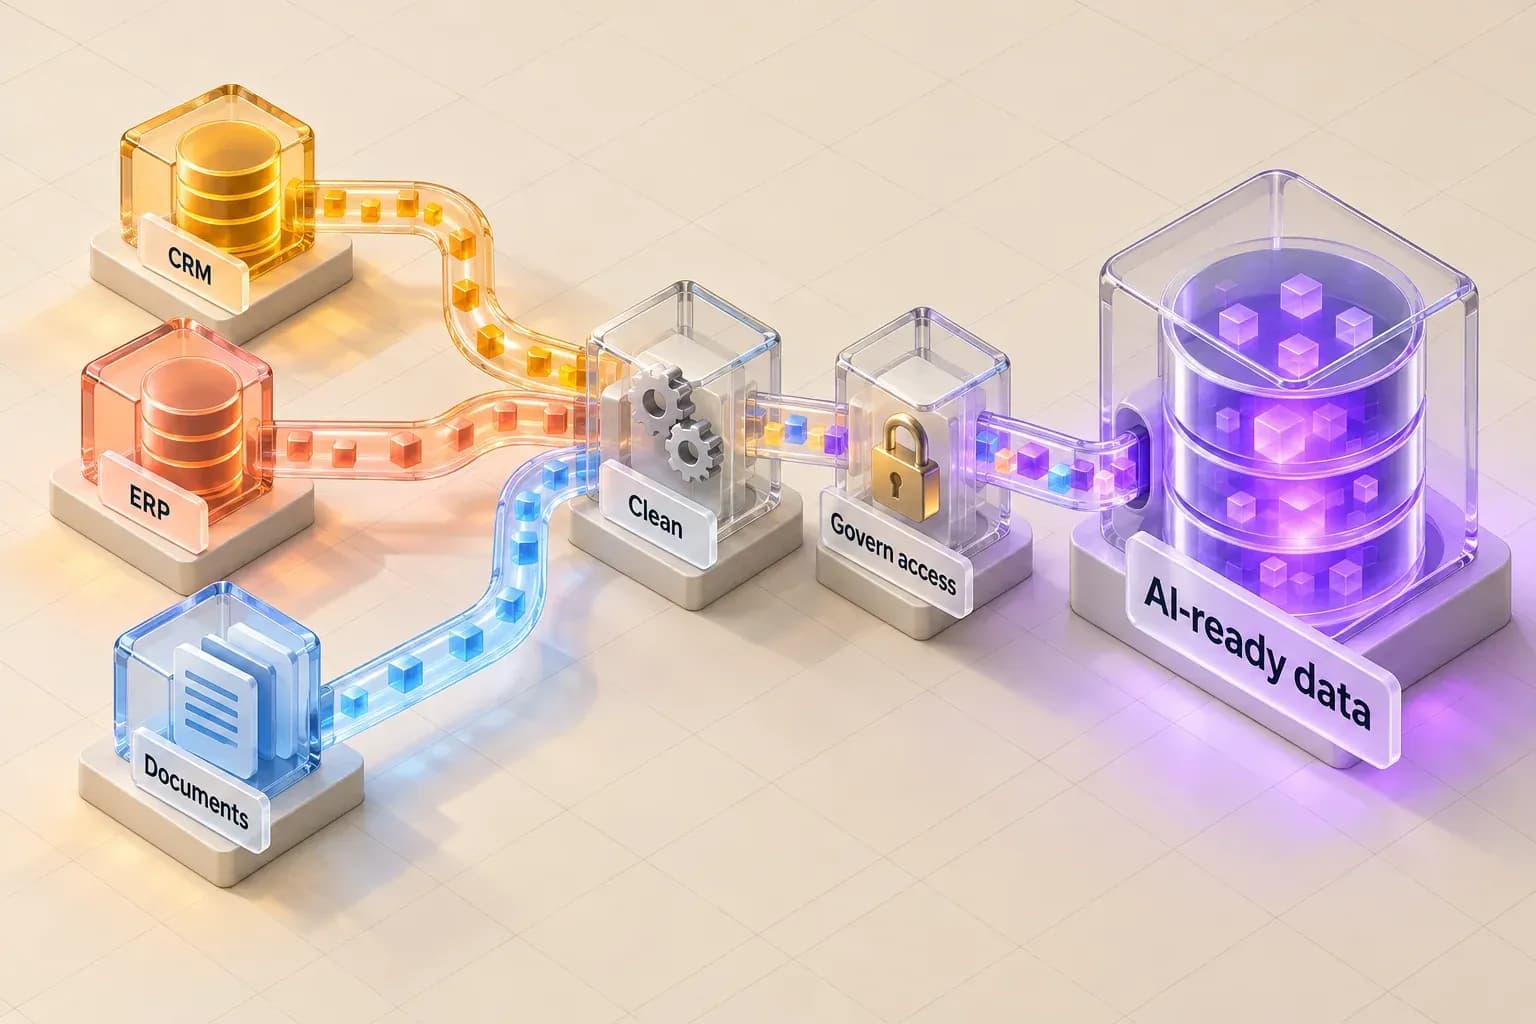
Most AI programs fail before a single model gets deployed, and the failure is invisible until it isn't: nobody wrote down what data the agents were allowed to touch, who owned it, or how it would stay accurate once three systems were writing to it at once. A data strategy for AI is the document and the operating agreement that answers those questions before you build anything that acts on the data, not after something goes wrong. Get it right and every agent, dashboard and automation you add afterward gets faster to ship and safer to trust. Skip it and you spend the next eighteen months debugging trust, not capability.
What a data strategy for AI actually covers
A data strategy for AI is the plan for four things: where the data an AI system will use actually lives, who is accountable for its accuracy, what it is and is not allowed to be used for, and how changes to any of that get reviewed before they ship. It is not a data warehouse diagram, and it is not a governance policy binder nobody reads. It is a working answer to "can this agent touch this record, and who signed off on that."
Traditional data strategy asked "how do we report on this." AI-era data strategy has to answer a harder question: "how do we let a system act on this, safely, without a person checking every step." That shift is why a strategy written for BI dashboards usually does not survive contact with an agent that reads a customer record, drafts a response and takes an action on it. The stakes moved from a wrong number on a chart to a wrong action taken on someone's account.
Four things that break first when it is skipped
Skip the strategy step and the same four failures show up, in roughly this order:
- Conflicting sources of truth. Two systems disagree about a customer's status, and the agent picks whichever one it queried first. Nobody notices until a customer does.
- No clear owner for a "wrong." When an agent acts on bad data, the postmortem takes a week because nobody can say who was responsible for that field being correct in the first place.
- Access creep. An agent gets broad read access "to be safe," because nobody defined the narrower scope it actually needed, and now every new agent inherits the same over-broad grant.
- Silent drift. A field's meaning changes upstream (a status code gets repurposed, a currency assumption shifts) and nothing downstream notices, because nothing was watching for it.
Each of these is cheap to prevent before an agent is reading the data and expensive to unwind after one has been acting on it for months.
What "AI-ready" data actually requires
"Clean data" is necessary but it is not the bar. AI-ready data adds three things a reporting-only strategy usually skips:
- Lineage that survives an agent's question. Not just where a number came from for a quarterly report, but where a specific field came from at the moment an agent read it, so a wrong action can be traced back to its source in minutes, not days.
- Scoped access, not blanket access. An agent that drafts customer emails needs read access to the fields that make the email accurate, not the whole customer record. Defining that scope is a data strategy decision, not an engineering afterthought.
- A review point before consequence, not after. The strategy should say, explicitly, which categories of action an agent can take on its own and which require a human to approve first. That line is a governance decision made once, not a judgment call made by whichever engineer ships the next feature.
This is where a data strategy for AI stops being a document and starts being an operating discipline: it has to be checked against every new agent and every new data source, not written once and filed away.
Building the strategy in a workable sequence
The programs that avoid the eighteen-month debugging cycle tend to do the same four things, roughly in this order:
- Inventory what data actually feeds decisions today, not what the data team wishes fed decisions. Most organizations discover the real inputs are messier and more manual than the architecture diagram suggests.
- Name an owner for each source, not each system. A source without a named accountable person is a source nobody will fix when it drifts.
- Define the access and action boundaries before the first agent goes live, using the categories above (read scope, action scope, approval requirement). This is the step most programs skip, and the one that costs the most to retrofit.
- Build the review loop last, not first. Decide how access and boundaries get revisited as new data sources and new agents are added, so the strategy stays a living agreement instead of a document from the kickoff meeting.
Sequencing matters because the first two steps are cheap and the third is where most of the real decisions live. Programs that jump straight to "let's define access boundaries" without the inventory step usually end up defining boundaries around the wrong data. If you are sequencing this alongside a broader rollout, a 90-day plan for moving from pilot to production is a useful frame for pacing the two together rather than treating data strategy as a prerequisite that has to finish first.
Where a governed AI workforce fits in
Archon Agents is a managed AI operations company. We build and operate governed AI workforces for organizations that need real execution, not another tool to manage, and a workable data strategy is the precondition for that, not a side project attached to it. The access and approval boundaries a strategy defines are the same boundaries a governed workforce enforces day to day: SSO, RBAC, approval queues, and audit logs are the operational form that "who can touch this, and who signed off" takes once the plan becomes a running system.
That is also why deployment model matters as much as the strategy document. Customer prompts, files, outputs, and workspace data are not used to train foundation models, and deployment runs on managed cloud, your private VPC, or fully on-premises, model agnostic by design. A data strategy that assumes strict data boundaries only works if the infrastructure underneath it actually holds those boundaries.
Most AI firms advise. Some sell tools. Archon operates the workforce, which means the data strategy question does not stop at the whiteboard. It has to hold up once agents are running against real records, every day, with a person in the loop wherever the strategy said one belongs.
FAQ
Is a data strategy for AI different from a general data governance policy? Related, but not the same document. A governance policy usually covers compliance and reporting. A data strategy for AI has to additionally define what an autonomous system is allowed to act on and when a human has to approve that action first, which a reporting-focused policy rarely addresses.
Do we need this before piloting our first AI agent, or can it wait? Define it before the pilot touches real customer or production data. A pilot on synthetic or sandboxed data can go first; anything acting on live records needs the access and approval boundaries settled beforehand, because retrofitting them after an agent has been running is the expensive path.
Who should own the data strategy inside the organization? Whoever is accountable for the decisions the AI system will influence, working with whoever owns the underlying data sources. It is a joint operating agreement between the business owner and the data owner, not a document IT writes alone.
How often does a data strategy for AI need to be revisited? Every time a new data source or a new agent is added, at minimum. The sequence above treats the review loop as a standing step, not a one-time deliverable, because the access boundaries that were correct for one agent are rarely still correct once a second and third agent are reading the same data.
Where to start
The fastest way to find out whether your data is actually ready for an AI system to act on it is to walk through the inventory step above against one real workflow, not the whole organization at once. Once the strategy is running, measuring whether it is actually working matters as much as writing it down in the first place. If that walkthrough surfaces more open questions than answers, that is normal, and it is exactly the conversation a Book a Consultation session is for. See how the access, approval and audit model behind a governed AI workforce works in practice on the security page, or get in touch to talk through where your own data stands today.